Vibe-coded apps break most often on access control, exposed secrets and baseline defences nobody asked for in the prompt. Veracode's testing of more than 100 models found 45% of security-sensitive samples introduced an OWASP Top 10 vulnerability, and Carnegie Mellon researchers found that while 61% of AI-generated code functions correctly, only 10.5% passes security review. Reducing that exposure does not require rewriting everything by hand. It requires controls outside the model: separated environments, default-deny data access, secrets kept out of source, scanning in the pipeline, and a human reading the diff wherever trust boundaries live.
The studies disagree on the number and agree on the shape
Every serious measurement of AI-generated code security lands in the same territory, which is the useful part. Veracode tested over 100 large language models on security-sensitive coding tasks and found that 45% of samples introduced an OWASP Top 10 vulnerability, a pass rate that did not improve across testing cycles from 2025 into early 2026. Carnegie Mellon’s figures split function from safety cleanly: 61% of generated code works, 10.5% survives a security review. A Stanford controlled study found participants using AI assistants wrote vulnerable code around 40% of the time on security-sensitive tasks, and rated that code as more secure than the code written without help. GitHub has disclosed that Copilot suggestions were vulnerable in roughly 30% of security-sensitive scenarios.
Those are laboratory conditions. The field data is worse, because in the field nobody stops to check. Escape.tech scanned 5,600 applications built with vibe coding tools and found more than 2,000 vulnerabilities, over 400 exposed secrets including API keys and tokens, and 175 instances of exposed personal data. A December 2025 CodeRabbit analysis of 470 open-source GitHub pull requests found that code co-authored by generative AI carried roughly 1.7 times more major issues than human-written code, with misconfigurations 75% more common and security vulnerabilities 2.74 times higher, as summarised on Wikipedia’s vibe coding entry. A large academic study presented at IEEE ISSRE 2025, covering over 500,000 Python and Java samples, found AI code contained more high-risk vulnerabilities despite being structurally simpler than the human-authored comparison set.
The most pointed result is the smallest sample. Tenzai examined 15 production applications built with five major tools, Claude Code, OpenAI Codex, Cursor, Replit and Devin, and found 69 vulnerabilities. Every single application lacked CSRF protection. Every single one shipped with no security headers configured. Every tool introduced a server-side request forgery flaw. CSO Online’s coverage of the study draws the distinction that matters: the tools are good at avoiding flaws that can be solved in a generic way, and struggle exactly where the line between safe and dangerous depends on context the model does not have.
Speed multiplies whatever you were already doing
There is a second effect underneath the vulnerability rate, and it is arithmetic rather than opinion. Veracode’s data shows AI-assisted developers committing code at three to four times the rate of their non-AI peers, with monthly security findings climbing from roughly 1,000 to more than 10,000 over six months. Syntax errors fell 76% and logic bugs fell 60% over the same period, so the code got cleaner in the ways a compiler and a test suite can see.
What rose were the flaws neither of those can see. Privilege escalation paths increased by 322%. Architectural design flaws increased by 153%. That is the signature of a process producing more structurally sound code with worse structural decisions inside it, faster than anyone is reviewing it. If you want the general version of that argument, the risks and limits of vibe coding page covers how the failure modes differ from ordinary software defects.
Where it actually breaks
Four clusters account for most of it, and they are worth naming separately because they need different fixes.
Broken access control. This is the top item on the OWASP Top 10 and the cause of most public vibe-coding breaches. The pattern is dull and repeated: an endpoint or a table that anyone can read because the authorisation check was never written, or because Row Level Security was left disabled while someone was getting the prototype working. A model asked to build a dashboard will build a dashboard. It does not know which rows belong to which tenant unless you tell it, and it will not object to returning all of them.
Secrets in source. A 2026 GitGuardian report on secret sprawl found that Claude Code-assisted commits exposed secrets more than twice as often as human-only commits, and hardcoded secrets in public GitHub commits rose 34% year on year in 2025, the largest single-year jump recorded. The mechanism is simple. A working example with the key inline runs; a working example reading from the environment needs configuration the model cannot set up for you, so the inline version is the one that survives the iterate loop.
Missing baseline defences. CSRF tokens, security headers, rate limits, request size limits. These are not clever attacks. They are the things a framework gives you if you switch them on, and a prompt-driven build switches on only what was asked for. Nobody asks for a Content-Security-Policy while they are trying to get the signup form to work.
Context-dependent flaws. Injection, SSRF, unsafe deserialisation and the rest of the family where the same line of code is fine in one place and exploitable in another. Checkmarx defines vibe coding as describing a problem in a few sentences to an LLM tuned for coding, which is precisely the setup in which the context that decides safety never reaches the model.
The word covers two different jobs
Contrast Security makes a point that is easy to skip past and shouldn’t be. The term is used ambiguously, and the ambiguity is itself a risk, because it conflates two methods with very different outcomes. Pure vibe coding means accepting generated code without review, testing or understanding, on the basis that it runs. Andrej Karpathy’s original description was to give in to the vibes and forget that the code even exists, which is an honest account of a weekend project and a catastrophic operating model for anything holding customer data. Responsible AI-assisted development keeps a human in control of the same tools.
IBM’s analysis argues that vibe coding security risks are not like ordinary security risks, and the distinction is about who understands the system. A flaw in code a team wrote has an owner who can reason about it. A flaw in code nobody has read has no such owner, which is why the fix takes longer than the build did.
Controls that reduce the exposure
None of this requires abandoning the tools. It requires putting the checks somewhere the model cannot talk its way past.
Start with environment separation, because it is the control with the largest blast radius. An agent with credentials to production has production access, whatever the prompt says about being careful. Replit’s agent deleting a company’s live database in July 2025, reported by Fortune at the time, is the reference case: the instruction not to touch it existed, and the permission to touch it also existed, and permission wins. That is the general principle behind guardrails that stop an AI agent breaking your app, which is that a guardrail lives in the runtime, not the instructions.
Make data access default-deny and then test it as a stranger. Switch Row Level Security on before the first table has rows in it, and check every endpoint while signed out and while signed in as the wrong user. This single exercise catches the category responsible for most of the public incidents, and it takes minutes rather than an audit.
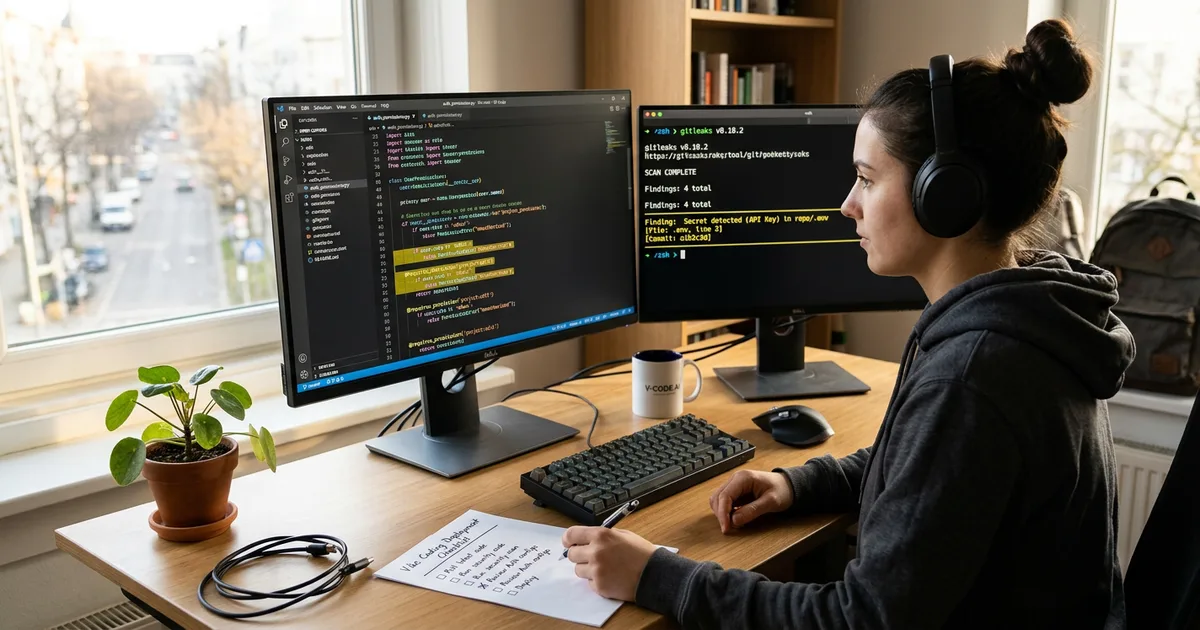
Get secrets out of the repository and assume some are already in the history. Environment variables or a managed secrets store, a scanner in continuous integration that fails the build on a detected credential, and rotation for anything that was ever committed. The Cloud Security Alliance’s research note on credential sprawl and SDLC debt sets out how quickly this accumulates once commit volume rises.
Name the security requirement in the prompt rather than hoping for it. Ask for parameterised queries, ask for the authorisation check, ask for CSRF protection and the headers, state which inputs are untrusted. This helps and it is not sufficient, which is the trade-off to hold in mind: asking improves the odds on the generic flaws and does nothing about the ones that depend on context the model still cannot see.
Read the diff where trust boundaries live. You do not have to read every line to get most of the benefit, but authentication, authorisation, anything touching money, anything handling file paths or outbound requests, and anything that writes to the database deserve a human pass. Reading the diff is the review vibe coding lacks sets out how to make that read fast rather than exhaustive.
Run automated scanning in the pipeline, and get an independent test before real users arrive. Static analysis, dependency scanning and secret detection on every change catch the known shapes cheaply. They will not find broken access control specific to your data model, which is what an external test is for. There is also a point at which the honest answer is to take over the code yourself, and the signals that you have reached it are worth knowing before you get there.
Write the rules down once, so they apply to everyone using the tools. Approved tools, review thresholds, what may never be pasted into a prompt, what must run in continuous integration. What your AI code policy must say on security and IP covers the shape of that document.
The trend line worth watching
Georgia Tech’s Systems Software and Security Lab launched the Vibe Security Radar in May 2025 to track CVE entries directly caused by AI-generated code. The counts climbed from 6 in January 2026 to 15 in February and 35 in March, reaching 74 catalogued entries by March 2026. Two named examples are CVE-2025-55526, a directory traversal flaw in n8n-workflows scoring 9.1 on CVSS, and GHSA-3j63-5h8p-gf7c, improper input handling in the x402 SDK, both linked to AI-generated code in August 2025 and both confirmed in the NVD and the GitHub Advisory Database respectively.
The researchers behind the tracker believe the catalogue undercounts the real figure by a factor of five to ten across the wider open-source ecosystem, a view echoed in the CSA note on the AI-generated CVE surge. That is the number to keep an eye on, because it measures something the vendor benchmarks cannot: not how often a model writes a flaw in a test, but how often one reaches software other people depend on.
Written with AI assistance and reviewed under our editorial policy. Vibe coding changes quickly; details reflect sources current on 2026-09-24. Some passages are the author's opinion. Spotted an error? tell us.
Frequently asked questions
- Does asking the AI to write secure code fix the problem?
- It helps with the generic flaws and does not solve the contextual ones. Naming parameterised queries, authorisation checks and CSRF protection in the prompt raises your odds on the patterns a model can apply in the abstract. The Tenzai study found every tool tested still introduced SSRF and shipped without security headers, because those depend on context the model does not hold.
- Which vibe coding platform is the most secure?
- The published testing does not support naming a winner. Tenzai found vulnerabilities across applications built with all five tools it examined, including Claude Code, Codex, Cursor, Replit and Devin, and Veracode found that larger models were not better than smaller ones at generating secure code. The controls around the tool matter more than the choice of tool.
- What is the single most valuable check to run first?
- Test your application while signed out and while signed in as the wrong user, on every endpoint and every table. Broken access control is the top OWASP risk and the cause of most publicised vibe-coding data exposures, and this check finds it in minutes without any tooling.
- Is a prototype safe to ship if no real users have it yet?
- A prototype behind authentication with no real data is a reasonable place to move fast. The line is real users or real data, and once either is present the exposure is live whether or not you announced the launch. Escape.tech's scan of 5,600 vibe-coded applications found 175 instances of exposed personal data, much of it in things nobody considered finished.