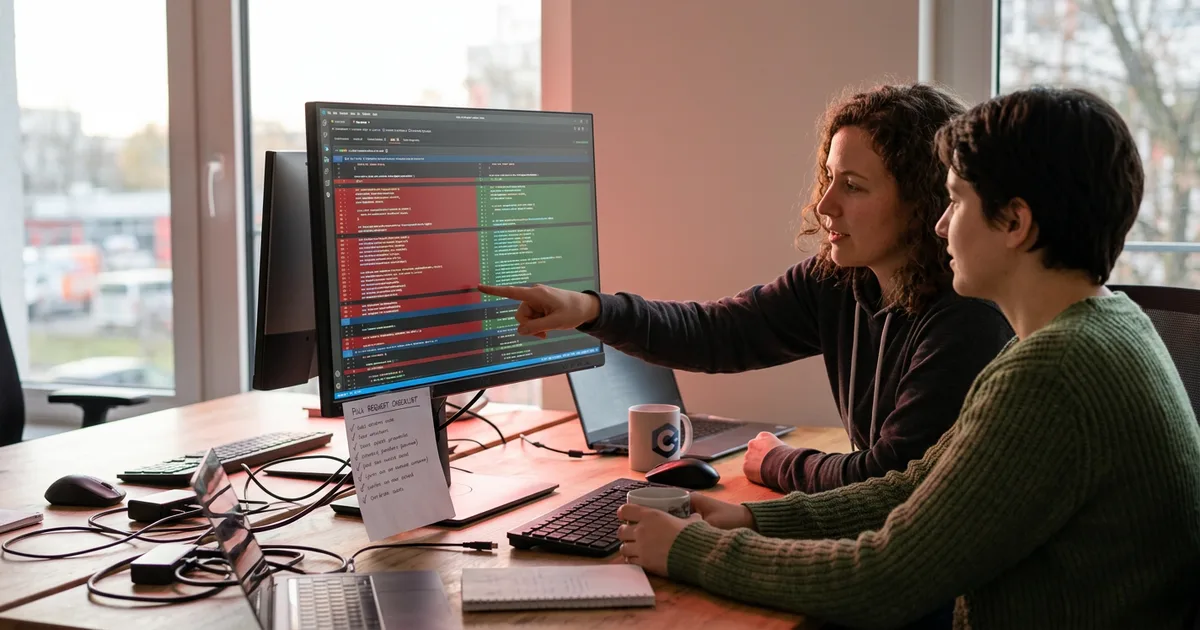
Structure a team review for AI-generated pull requests around disclosure, stated intent, a size cap and a fixed reading order. Those four come up again and again in current guidance because AI pull requests fail differently from hand-written ones: the intent is missing rather than implied, the diffs are larger, and the person submitting may not have read the code either. The rest is triage. At the volumes AI coding for business now produces, nobody reads every line honestly, so attention has to go where a mistake is expensive: authentication, payments, data handling, and anything hard to undo.
The bottleneck moved to review
For twenty years the slow part of shipping software was writing it. That is no longer true in teams using agents seriously, and the queue has simply moved one step along. Code arrives faster than humans can read it, and the people doing the reading are the same people who were already stretched.
Google is the usual bellwether here. Google Cloud’s own piece on who reviews the code treats the question as open rather than solved.
Say plainly which parts the model wrote
The first structural change costs nothing: put AI involvement in the pull request template as a required field. Not a vague tick box labelled “used AI”, but a short statement of what the model did. Suggested a few lines. Wrote the whole module. Generated the tests. Touched the config. Several current guides recommend exactly this, and the reason is practical rather than bureaucratic: a reviewer who knows the tests were generated by the same run that wrote the code will read those tests differently, and should.
Disclosure also gives you a record. If you are tracking where defects cluster, or where your reviewers spend time, you need to be able to separate generated changes from hand-written ones six months later. Without a field in the pull request, that information is gone the moment the branch is deleted. This is the same argument for keeping an authorship record that runs through what an AI code policy must say about security and IP, and the two records are usually the same record.
The field should be honest rather than flattering, which means nobody should be penalised for ticking “generated”. A disclosure field that carries a social cost gets filled in wrongly, and then you have worse data than none.
Require the reasoning before anyone opens the diff
A human-authored pull request carries intent implicitly. The author made choices, and when a reviewer asks why a check was moved, the author remembers. Generated code does not carry that. The model made choices for reasons that were never articulated, and if the submitter did not interrogate them, the reasoning does not exist anywhere.
So make it exist. Have the agent explain what it did before you read the diff, and have it state what it deliberately did not do. The second half is the valuable one. “I did not change the session handling, and the new endpoint relies on the existing middleware being applied” is a sentence that tells a reviewer precisely where to look. Several of the guides in circulation put it bluntly: no stated reasoning, no review, send it back.
This works because it reverses the asymmetry described in reading the diff is the review vibe coding lacks. Generation is cheap and review is expensive, so anything that narrows where a reviewer has to look buys back real time. A written rationale, plus a linked ticket recording the requested behaviour and acceptance criteria, turns an opaque change into something you can check against a claim.
It also catches a specific failure: the agent that confidently reports success having done something adjacent to what was asked. If the stated reasoning does not match the ticket, you have found the problem before reading a single line of code.
Give agents a size budget
If AI pull requests run larger, and reviewer capacity has not changed, the arithmetic does not work. Setting line and file budgets for agent output is the least glamorous fix available and probably the most effective. Pick a number your reviewers can genuinely hold in their heads, and treat anything over it as a submission that needs splitting rather than approving.
The important part is the enforcement. A diff too large to review honestly should be rejected, not skim-read and waved through, because a reflexive approval is worse than no review at all: it creates a record saying a human checked something nobody checked. Rejecting large diffs sounds harsh until you watch it work. The agent is perfectly capable of producing the same change in four pieces, and the four pieces are each reviewable.
This is the same discipline argued for in small iterations beat big rewrites in vibe coding, applied at the team boundary rather than the individual one. Size caps on pull requests also push work into the shape where agents perform best, so you are not trading speed for reviewability as much as it first appears.
Some teams go further and route agent-generated pull requests into a separate queue with its own policy: different reviewers, different checks, different expectations about turnaround. That is worth considering once generated changes are a meaningful share of your volume, because mixing them into the general queue means every reviewer context-switches between two quite different jobs.
Read removals first, then imports, then logic
The reading order matters more than most teams expect, and the recommended order is counter-intuitive. Start with what was deleted.
Generated changes remove things that look unnecessary in the immediate context and are load-bearing elsewhere. A validation check. An error handler. A logging line that someone added after an incident. A compatibility branch for the one client still on the old payload. The model has no memory of why any of that is there, and a diff viewer shows removals in a colour nobody lingers on. Reading the deletions first, deliberately, catches the class of regression that is hardest to find later.
Second, read the imports and the lockfile. An agent reaches for a package the way the rest of us reach for coffee, and
Written with AI assistance and reviewed under our editorial policy. Vibe coding changes quickly; details reflect sources current on 2026-11-01. Some passages are the author's opinion. Spotted an error? tell us.
Frequently asked questions
- Should every AI-generated pull request have a human reviewer?
- Yes, and the reviewer should be accountable for what merges rather than for having skimmed it. GitHub's guidance is explicit that human accountability does not transfer to the tool. What can change is depth: triage lets you read some changes closely and others quickly, so long as the allocation is deliberate.
- How large is too large for an AI-generated pull request?
- Large enough that a reviewer cannot honestly hold the whole change in their head, which varies by team and codebase. Set a line and file budget that matches your actual reviewer capacity and treat anything over it as a submission to split. A diff too big to review should be rejected rather than approved on trust.
- Does an AI code reviewer remove the need for human review?
- No. An AI reviewer shares the blind spots of the AI author, which is why Anthropic's engineering team noted that their review runs with the same model rather than a second one. Automated review is good at mechanical issues and poor at spotting a change that is wrong because the requirement was misunderstood.
- Should the pull request record which model wrote the code?
- Recording the model and the extent of its involvement is useful for two reasons: reviewers read generated tests differently from hand-written ones, and you need the record months later when tracing where defects cluster. Keep the field blame-free, because a disclosure that carries a social cost gets filled in dishonestly.