Use an agentic coding tool when the task spans several files and something other than your own reading can confirm it worked, and an inline assistant when you already know the code you want and only need it typed faster. The two are not competing products so much as two modes of working, and most of the major tools now ship both, so the choice is made per task rather than once at purchase. What actually separates them is who owns the task: an inline assistant reacts to your cursor and stops when you stop, while an agent takes a goal, plans, edits, runs things, reads the result and goes again. That autonomy is worth having when the work is broad and checkable, and a liability when it is small, rule-driven or risky to get wrong.
The difference is who owns the task
An inline assistant is tied to your cursor. It watches what you are typing and predicts the next line, function or block from the file in front of it, and its usefulness is bounded by how well the surrounding code already states your intent. Classic Tab completion in GitHub Copilot is the canonical version: reactive, cursor-local, and not agentic in any meaningful sense.
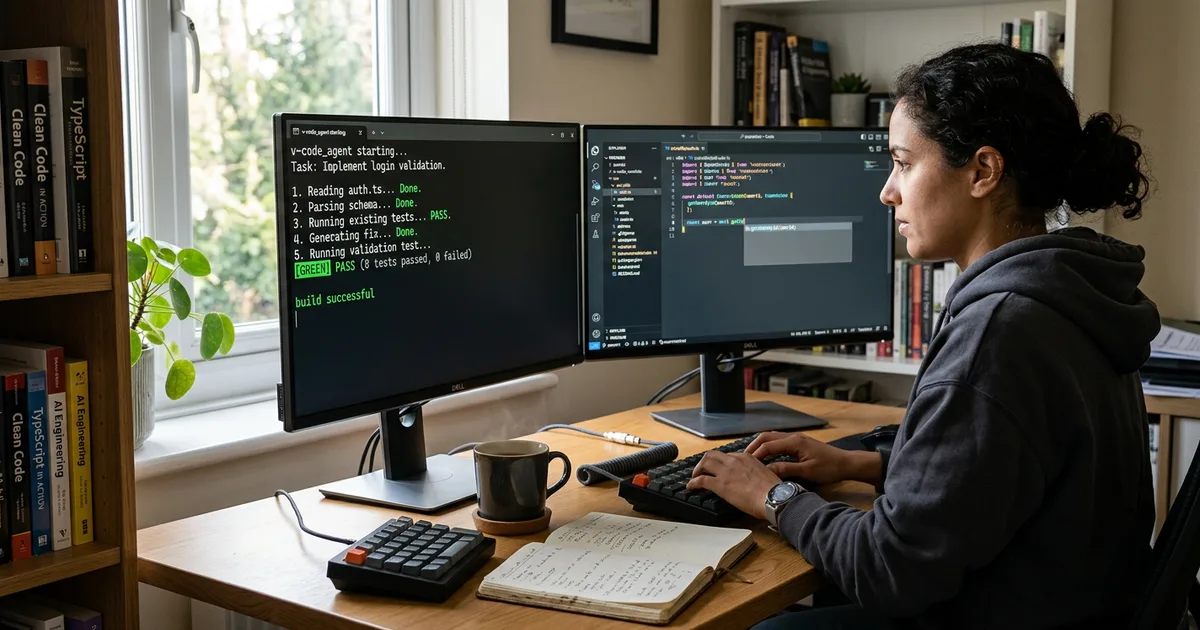
An agentic tool inverts the relationship. You give it a goal in plain language, and it breaks that goal into steps, edits files, runs commands, reads what came back, diagnoses failures and repeats until the work is done or it needs you. Pickuma frames the split as inline completion augmenting typing while agentic coding augments planning and execution, which is the clearest one-sentence version of it I have read. The technical markers are a planning layer, context that persists across steps, and permission to use tools without being asked each time, and Augment Code treats those as architectural gaps rather than feature differences, which is right. You cannot bolt a plan onto a completion engine.
Both modes sit on a spectrum, not either side of a wall. Copilot began as inline completion, added chat, then pull request summaries, then agent modes that identify relevant files, propose multi-file changes and suggest terminal commands. Anthropic’s Claude Code went the other way, starting terminal-native and agentic: it reads the project, plans, edits across files, runs tests, handles failures and commits. MindStudio’s comparison sets those two heritages against each other, and the heritage still shows in how each one feels to use even now that the feature lists overlap.
Where an inline assistant is still the right choice
The honest case for autocomplete is that most code you write in a day is not interesting. It is a mapper between two shapes you already understand, a test that follows the pattern of the four tests above it, a config block whose keys you half remember. You know what you want. You just want it on the screen faster than you can type it, and you want the loop to be instant.
That is exactly the work an assistant is built for, and it is work an agent handles badly. Handing a one-file change to an agent means writing a paragraph of instruction, waiting through a plan, and then reading a diff you could have written in the time it took to describe. The overhead is real and it is paid every time.
Inline completion also holds its value when you are working inside code you do not fully trust yourself in. Suggestions arrive one at a time, in context, and you accept or reject each one while your attention is already on that line. The review is free because you are looking at the spot the change lands. Tool round-ups such as Qodo’s tested comparison note the low learning curve of this model too, and that matters more than it sounds: the interaction is autocomplete, which every developer already understands, so nothing has to be learned before the first useful day.
When to reach for an agent
Four signals, and the more of them a task shows, the stronger the case.
The change spans files. A rename that ripples through imports, a refactor that moves a responsibility from one module to three, a framework upgrade that touches every route. This is where an assistant’s cursor-local view stops helping, because the thing you need is consistency across places you are not currently looking.
The task needs execution, not just text. Anything with an edit, run, inspect rhythm: chasing a failing test, tracking down why the build breaks only in CI, working through a stack trace whose cause is two layers below where it surfaced. An agent that can run the test suite and read the output closes that loop without you being the messenger between the model and the terminal.
The unit of work is a ticket rather than a function. Delegating “add a login flow” means models, routes, views and tests, and an agent that plans before it types can carry that shape. It is now normal for an engineer to assign an issue to an agent rather than to themselves and review the resulting pull request, and the tools built for that pattern are numerous enough to need their own survey, which is what the vibe coding tool guide on this site is for.
The work can run unattended. Practising engineers describe the two modes in almost domestic terms: an inline assistant is a very fast colleague pairing with you, and an agent is a task handed to a junior engineer overnight. Same person, same week, different tasks. That is the healthy pattern, and anyone insisting on one mode for everything is optimising for tidiness rather than output.
Verifiability decides more than scope does
Scope tells you whether an agent can help. Verifiability tells you whether you should let it. Amplifi Labs puts it plainly: agentic AI becomes compelling when tasks are clearly defined and easy to validate. The reason is arithmetic. An agent’s speed comes from doing many steps between your inputs, so the diff you get back is large. If the only way to know whether it is correct is for a human to read all of it, you have moved the bottleneck rather than removed it.
A failing test you can hand over, a lint rule, a type checker, a build that either passes or does not, a script that reproduces the bug: these are what let an agent verify itself and let you trust the summary. Absent that, you are back to reading everything, which is the asymmetry covered in why reading the diff is the review vibe coding lacks. Generation got cheap. Review did not.
This is also why the strongest agentic results tend to appear on benchmarks with automatic pass conditions. Open agents are reported at around 72% on SWE-bench Verified with a current frontier model in Agentic.ai’s round-up of coding agents, and that number is meaningful precisely because the benchmark can check the answer. Your own repository is only as agent-friendly as its ability to do the same.
When an agent is the wrong tool
Agency has a cost, and the general guidance on agentic systems is more sceptical than the marketing around individual products. Anthropic’s own engineering write-up on building effective agents argues for finding the simplest thing that works and adding autonomy only when it earns its keep. Four cases where it does not.
Simple, repeatable, rule-driven work. If the transformation is deterministic, write the script. A codemod that runs the same way every time beats a model that might.
Tight latency. Nothing about a plan, execute, verify loop is fast. If you need the suggestion inside the second, an agent is the wrong shape.
High-risk or compliance-heavy actions without approval gates. Anything touching production data, payments, access control or personal data needs a human between the intent and the effect, and that means explicit gates rather than a general instruction to be careful. Which tools are approved for which work is a policy question, not a preference, and it belongs in writing alongside the rest of what an AI code policy has to say on security and IP.
Low tool reliability where failure is expensive. An agent that can run commands in an environment with no rollback is a bad trade at any speed.
The supervision cost nobody prices in
The hidden expense of agentic work is not tokens, it is attention. A long unattended run produces a large change set, and reviewing a large change set well is slow, tiring work that does not compress. Teams that get good results narrow the leash: smaller scoped tasks, a written project brief the agent reads before it starts, tests that fail before the work begins, and a habit of stopping the run when the plan looks wrong rather than waiting to judge the output. Anthropic’s own Claude Code documentation is largely about exactly this kind of setup, which tells you something about where the difficulty actually sits.
The same working habits apply whichever mode you are in, and they are collected in the guide to reliable rather than lucky results on this site. Small slices, stated constraints, a real example, and a review you can actually perform. None of that changes because the tool got more autonomous. It just matters more, because the change arriving on your screen is bigger.
A rule you can hold in your head
Ask two questions before you start. Does this change touch more than the file I am looking at? Can something other than my own reading tell me it worked?
Both yes: give it to an agent, scope it to one ticket, and make sure the check it needs exists before you press go. Either no: stay at the cursor and let completion save you the typing. First yes and second no: do the work yourself, or spend twenty minutes writing the test that turns the second answer into a yes, which is usually the better investment anyway.
Since most current tools offer both modes, this is a decision you make several times a day rather than once a year. Reviews such as Axify’s comparison of AI coding assistants show how thoroughly the two capability sets have merged across the market, which removes the excuse of blaming the tool. The judgement is yours, and it is about the task in front of you, not the logo on the sidebar. If you want the mechanics underneath both modes, how vibe coding works sets out the prompting, context and review loop they share.
Written with AI assistance and reviewed under our editorial policy. Vibe coding changes quickly; details reflect sources current on 2026-09-10. Some passages are the author's opinion. Spotted an error? tell us.
Frequently asked questions
- Is an agentic coding tool just a better autocomplete?
- No, they are different architectures rather than different quality tiers. An inline assistant predicts text at your cursor from the current file, while an agent has a planning layer, context that persists across steps, and permission to run tools on its own. That autonomy is what makes it useful for multi-file work and what makes it unsuitable for a one-line change.
- Do I have to choose one tool for the whole team?
- Not really, because most major products now offer both inline completion and an agent mode, so the choice is which mode to use for a given task. What is worth standardising is the approval list and the review threshold, not the editor. Those belong in a written policy so nobody has to guess what is allowed.
- How do I stop an agent producing a diff too large to review?
- Scope the task to one ticket, make the failing test exist before the run starts, and read the plan rather than waiting for the output. If the plan looks wrong, stop the run instead of correcting the result. Smaller slices cost more prompts and save far more review time.
- What kind of task should never go to an agent?
- Deterministic, rule-driven transformations are better handled by a script, and anything touching production data, payments or access control needs an explicit human approval gate rather than a general instruction to be careful. Work with very tight latency requirements is also a poor fit, since a plan, execute and verify loop is never fast.